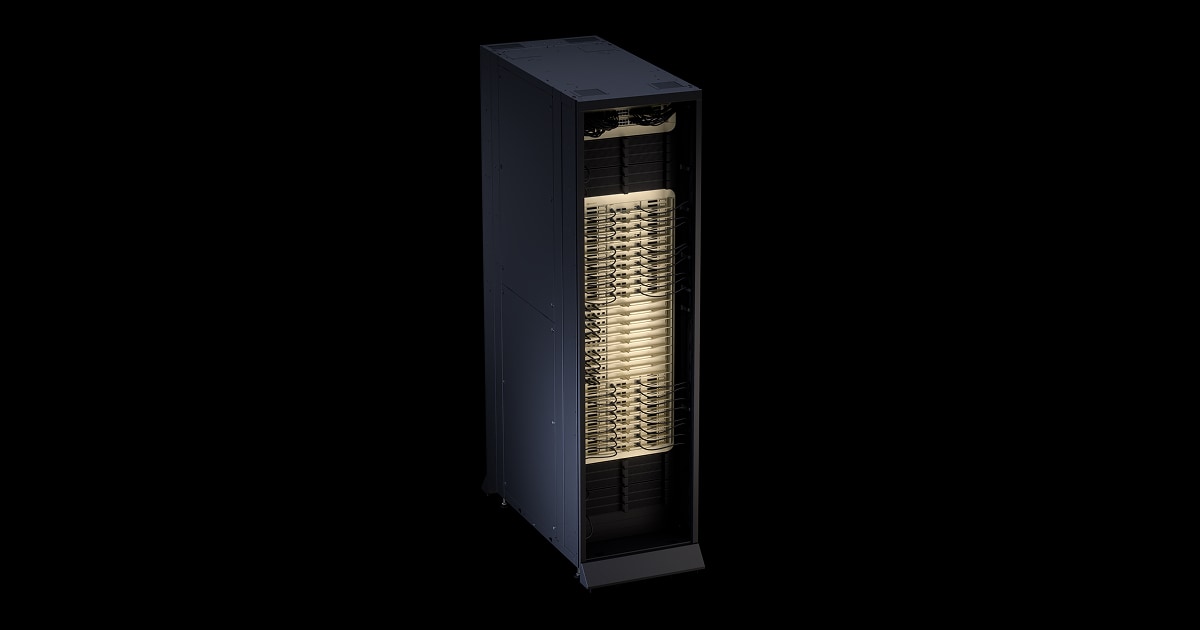
NVIDIAVera Rubin NVL72
The next-generation infrastructure for building AI agents
Unify 72 NVIDIA Rubin GPUs, 36 Vera CPUs, ConnectX-9 SuperNICs, and BlueField-4 DPUs into a single rack-scale platform delivering 3,600 PFLOPS of NVFP4 inference performance and 20.7TB HBM4 memory. Built on the third-generation MGX NVL72 rack design, it provides powerful compute for large-scale pre-training, post-training, and real-time agent inference.
Seven new chipsAn AI supercomputer
NVIDIA Vera Rubin NVL72 integrates NVIDIA's cutting-edge technologies, enabling vertical scaling within racks via sixth-generation NVLink switches and horizontal scaling through Quantum-X800 InfiniBand and Spectrum-X Ethernet. Compared to the Blackwell platform, it reduces the number of GPUs required for AI training by 75% and lowers inference costs per million tokens to one-tenth, providing a scalable compute foundation for the era of agentic AI.
DriverThe Era of AI Agents
From chip integration to inference economics, from training efficiency to rack design, Vera Rubin NVL72 delivers full capabilities for AI factories.
Unified AI Supercomputer with Multi-Chip Architecture
Unify 72 NVIDIA Rubin GPUs, 36 NVIDIA Vera CPUs, ConnectX-9 SuperNICs, and BlueField-4 DPUs on a rack-scale platform. Scale vertically via 6th-generation NVLink switching and horizontally using Quantum-X800 InfiniBand and Spectrum-X Ethernet.
Dual optimization of inference cost and throughput
For AI agents designed for high interactivity and deep reasoning, the cost per million tokens is approximately one-tenth of GB200 NVL72, with token output per megawatt increasing up to 10 times. When deployed alongside Groq 3 LPX, throughput per megawatt for trillion-parameter models can rise up to 35 times.
Significantly improved training efficiency
Training mixed expert (MoE) models requires only one-quarter the number of GPUs compared to GB200 NVL72, enabling large-scale training tasks within the same timeframe and freeing up more compute resources for AI factories.
Third-Generation MGX Rack Design
Built on the third-generation NVIDIA MGX NVL72 architecture for seamless migration from previous platforms. Features a cable-free modular tray design and is supported by over 80 MGX ecosystem partners for rapid deployment.
NVIDIA Vera Rubin NVL72Technical Specifications
Complete parameter overview. Contact our technical consultant for selection advice.
| Settings | 72 NVIDIA Rubin GPUs | 36 NVIDIA Vera CPUs |
| NVFP4 Inference | 3,600 PFLOPS (sparse)* |
| NVFP4 Training | 2,520 PFLOPS (dense) |
| Train FP8/FP6 | 1,260 PFLOPS (dense) |
| FP16/BF16 | 288 PFLOPS (dense) |
| TF32 | 144 PFLOPS (dense) |
| FP32 | 9,360 TFLOPS |
| FP64 | 2,400 TFLOPS |
| GPU VRAM | Bandwidth | 20.7 TB HBM4 | 1,400 TB/s |
| NVLink | 6th-Gen NVLink, 216 TB/s bandwidth |
| NVLink-C2C bandwidth | 65 TB/s |
| CPU Cores | 3,168 Custom NVIDIA Olympus Cores | 6,336 Threads |
| CPU Memory | Up to 54 TB LPDDR5X |
| Network Bandwidth | 32.4 TB/s (bidirectional) |
| Total Chip Count | 1,296 (NVIDIA chip + HBM4 chip) |
| Rack Design | 3rd Generation NVIDIA MGX NVL72 Rack with Cable-Free Modular Tray Design |
| Inlet Temperature | 45°C |
* NVFP4 inference uses sparse specifications, while training uses dense specifications; network bandwidth is bidirectional. Specification parameters are sourced from NVIDIA's official product page; actual configurations are subject to factory settings.
Product BrochureDownload
Below is a preview of the NVIDIA Vera Rubin NVL72 product brochure. Click the button to generate and download the PDF version for internal review and selection archiving.
The Vera Rubin NVL72 unifies 72 Rubin GPUs, 36 Vera CPUs, ConnectX-9 SuperNICs, and BlueField-4 DPUs in a rack-scale platform, delivering 3,600 PFLOPS of sparse NVFP4 inference performance, 20.7TB HBM4 memory, and 216 TB/s of sixth-generation NVLink bandwidth. Compared to the GB200 NVL72, it reduces inference cost per million tokens by 10x and cuts the number of GPUs required for training MoE models by 75%.
| Settings | 72x Rubin GPU + 36x Vera CPU |
| NVFP4 Inference | 3,600 PFLOPS (sparse) |
| NVFP4 Training | 2,520 PFLOPS (dense) |
| Train FP8/FP6 | 1,260 PFLOPS (dense) |
| GPU VRAM | Bandwidth | 20.7 TB HBM4 | 1,400 TB/s |
| CPU Memory | Up to 54 TB LPDDR5X |
| NVLink Bandwidth | 216 TB/s (Sixth Generation) |
| Network Bandwidth | 32.4 TB/s (bidirectional) |
| CPU Core | 3,168 custom Olympus cores |
| Rack Design | Third-Generation MGX NVL72 · Cable-Free Tray |
Brochures are generated in real-time from page content. If your browser blocks the download, allow pop-ups and try again.
Ready to deploy Vera Rubin NVL72?
Huaying Technology provides end-to-end professional services for Vera Rubin NVL72 selection consulting, AI factory planning, and deployment implementation.
Purchase Intent
Submit your requirements and contact details. A sales consultant will confirm pricing, stock availability, and delivery options with you. Product prices are subject to quotation.