NVIDIA H100
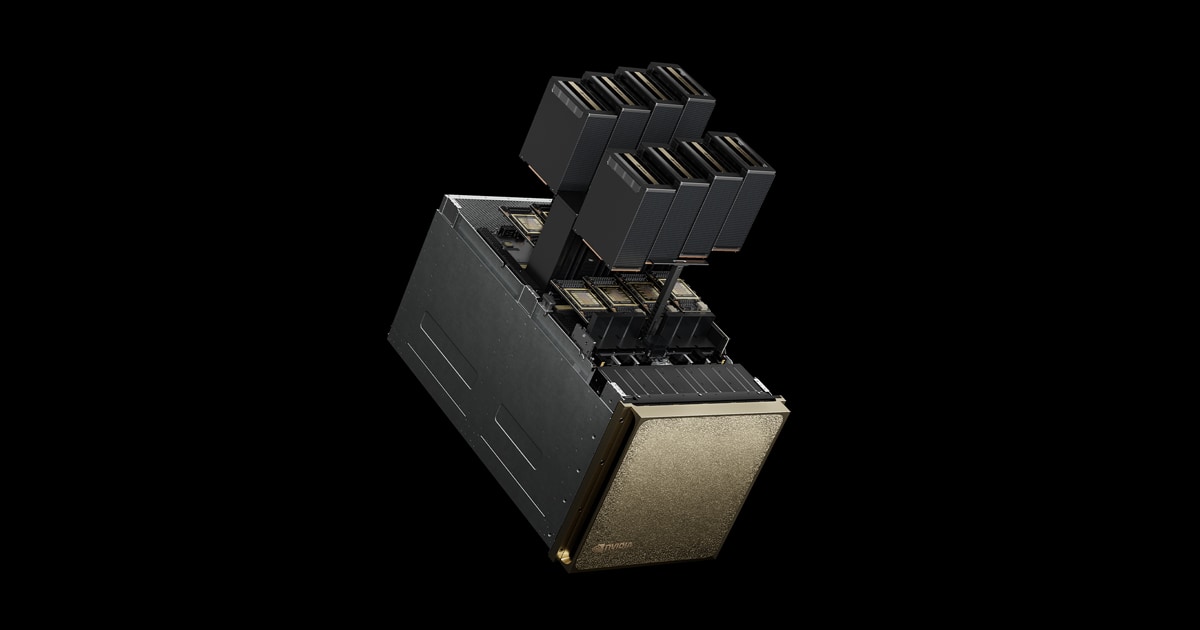
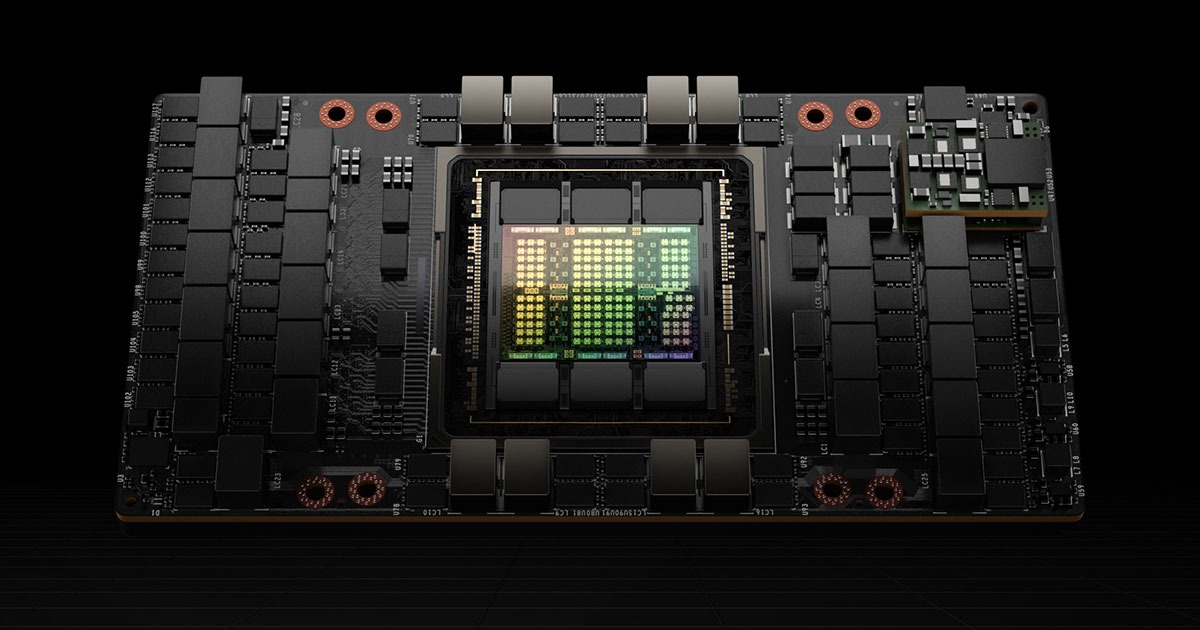
The NVIDIA H100 is a data center GPU based on the Hopper architecture, available in SXM, PCIe, and H100 NVL form factors. It features up to 80 GB of HBM3 memory (with 4 GB per card for the NVL version), offers fourth-generation NVLink bandwidth of 900 GB/s, supports Multi-Instance GPU (MIG), and serves as a leading compute platform for large model training, HPC, and large-scale inference.
Core Specifications
CompleteSpecifications
| architecture | Hopper |
| Shape | SXM5 / Dual-PCIe Slot / Dual-NVL |
| GPU VRAM | 80GB HBM3 (SXM/PCIe); 94GB HBM3 (per NVL card) |
| Memory Bandwidth | 3.35 TB/s (SXM) | 2 TB/s (PCIe) | 3.9 TB/s (NVL) |
| FP8 Tensor Core | Up to 3,958 TFLOPS* (SXM sparsity) |
| FP16/BF16 Tensor Core | Up to 1,979 TFLOPS* (SXM sparsity) |
| TF32 Tensor Core | Up to 989 TFLOPS* (SXM sparsity) |
| NVLink | 4th-Gen NVLink, 900 GB/s |
| MIG | Maximum of 7 instances |
| Power Consumption | 700W (SXM) | 350W (PCIe) | 400W (per card, NVL) |
| Location | Large-scale model training, HPC, and large-scale inference |
* Sparse mode specifications: Dense performance is half that of sparse specs. Specs sourced from NVIDIA's official product page; actual configuration subject to factory settings.
Product BrochureDownload
Below isNVIDIA H100Product Brochure Preview: Click the button to generate and download a PDF version for internal review and selection archiving.
The NVIDIA H100 is a data center GPU based on the Hopper architecture, available in SXM, PCIe, and H100 NVL form factors. It features up to 80 GB of HBM3 memory (with 4 GB per card for the NVL version), offers fourth-generation NVLink bandwidth of 900 GB/s, supports Multi-Instance GPU (MIG), and serves as a leading compute platform for large model training, HPC, and large-scale inference.
| architecture | Hopper |
| Shape | SXM5 / Dual-PCIe Slot / Dual-NVL |
| GPU VRAM | 80GB HBM3 (SXM/PCIe); 94GB HBM3 (per NVL card) |
| Memory Bandwidth | 3.35 TB/s (SXM) | 2 TB/s (PCIe) | 3.9 TB/s (NVL) |
| FP8 Tensor Core | Up to 3,958 TFLOPS* (SXM sparsity) |
| FP16/BF16 Tensor Core | Up to 1,979 TFLOPS* (SXM sparsity) |
| TF32 Tensor Core | Up to 989 TFLOPS* (SXM sparsity) |
| NVLink | 4th-Gen NVLink, 900 GB/s |
| MIG | Maximum of 7 instances |
| Power Consumption | 700W (SXM) | 350W (PCIe) | 400W (per card, NVL) |
| Location | Large-scale model training, HPC, and large-scale inference |
Brochures are generated in real-time from page content. If your browser blocks the download, allow pop-ups and try again.
Purchase Intent
Submit your requirements and contact details. A sales consultant will confirm pricing, stock availability, and delivery options with you. Product prices are subject to quotation.